dumpstool logo
You have a Fabric tenant that contains JSON files in OneLake. The files have one billion items.
You plan to perform time series analysis of the items.
You need to transform the data, visualize the data to find insights, perform anomaly detection, and share the insights with other business users. The solution must meet the following requirements:
♦ Use parallel processing.
♦ Minimize the duplication of data.
♦ Minimize how long it takes to load the data.
What should you use to transform and visualize the data?
You have a Fabric workspace named Workspace1 that contains an eventstream named Eventstream1.
Eventstream1 reads data from an Azure event hub named Eventhub1.
Eventhub1 contains the following columns.
Name
Data type
MachineId
Int
Payload
Dynamic
Datetime
Datetime
Location
String
You need to add a continuous percentile calculation to the Payload column. The solution must minimize development effort.
What should you do?
You have a Fabric tenant that contains a semantic model.
You need to prevent report creators from populating visuals by using implicit measures.
What are two tools that you can use to achieve the goal? Each correct answer presents a complete solution.
NOTE: Each correct answer is worth one point.
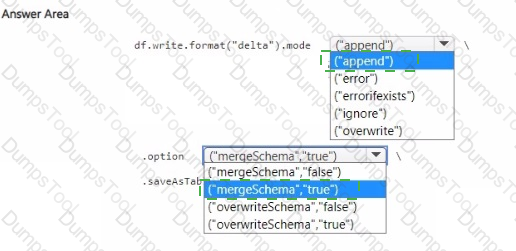
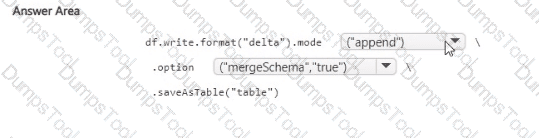
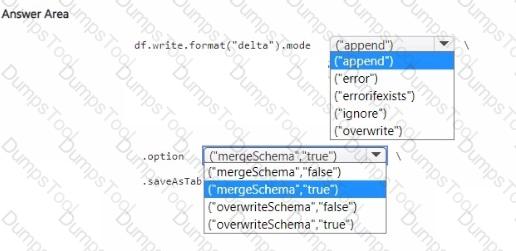
You have a Fabric tenant that contains lakehouse named Lakehouse1. Lakehouse1 contains a Delta table with eight columns. You receive new data that contains the same eight columns and two additional columns.
You create a Spark DataFrame and assign the DataFrame to a variable named df. The DataFrame contains the new data. You need to add the new data to the Delta table to meet the following requirements:
• Keep all the existing rows.
• Ensure that all the new data is added to the table.
How should you complete the code? To answer, select the appropriate options in the answer area.
You need to create a data loading pattern for a Type 1 slowly changing dimension (SCD).
Which two actions should you include in the process? Each correct answer presents part of the solution.
NOTE: Each correct answer is worth one point.
What should you recommend using to ingest the customer data into the data store in the AnatyticsPOC workspace?
You need to ensure the data loading activities in the AnalyticsPOC workspace are executed in the appropriate sequence. The solution must meet the technical requirements.
What should you do?
You need to implement the date dimension in the data store. The solution must meet the technical requirements.
What are two ways to achieve the goal? Each correct answer presents a complete solution.
NOTE: Each correct selection is worth one point.
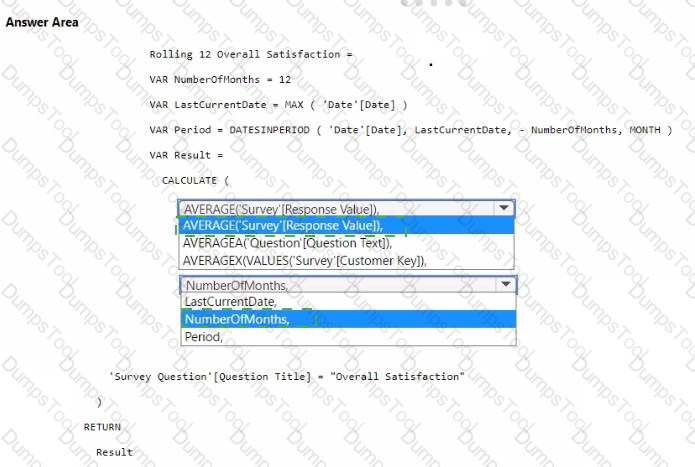
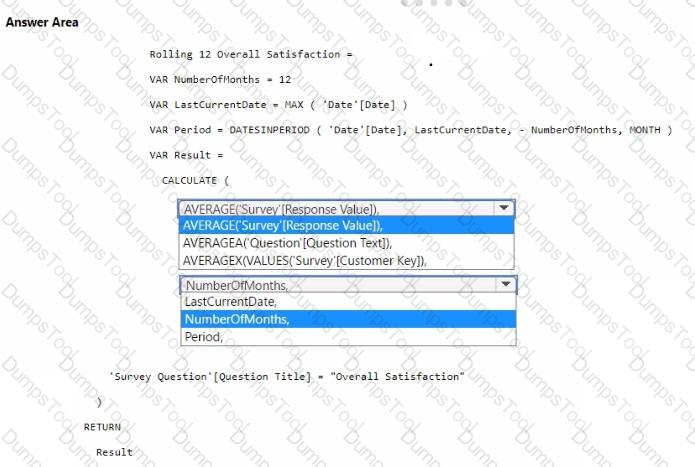
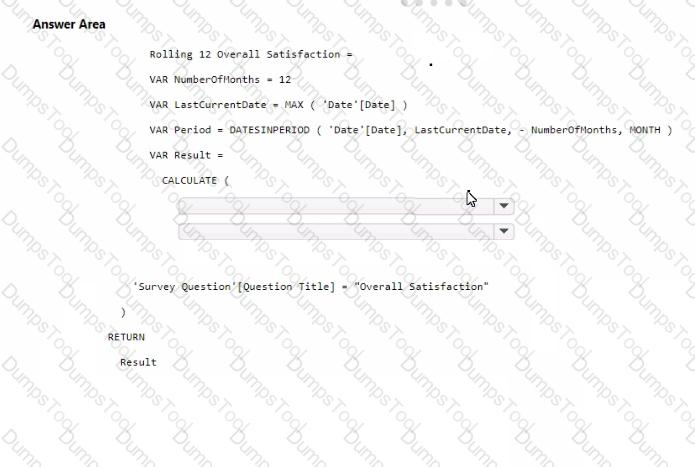
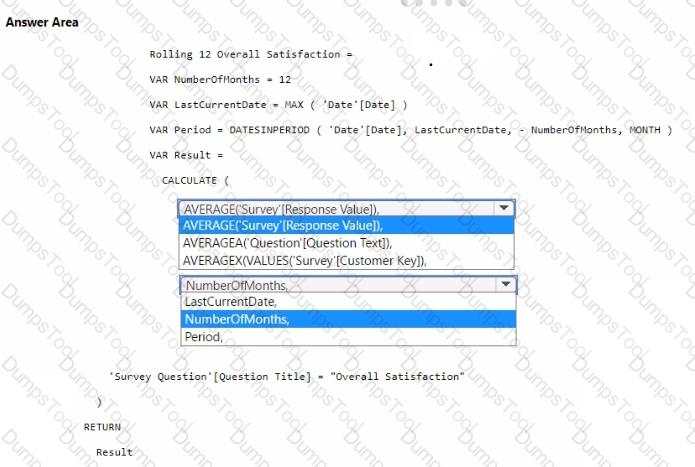
You need to create a DAX measure to calculate the average overall satisfaction score.
How should you complete the DAX code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
You need to recommend a solution to prepare the tenant for the PoC.
Which two actions should you recommend performing from the Fabric Admin portal? Each correct answer presents part of the solution.
NOTE: Each correct answer is worth one point.
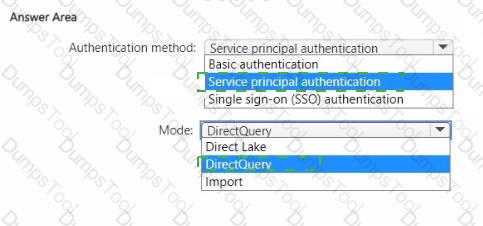
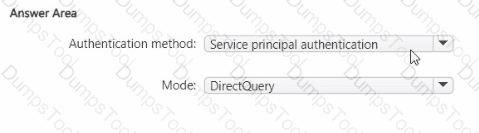
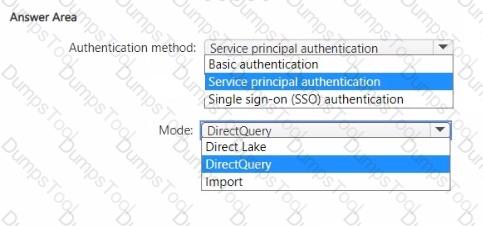
You need to design a semantic model for the customer satisfaction report.
Which data source authentication method and mode should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Which type of data store should you recommend in the AnalyticsPOC workspace?
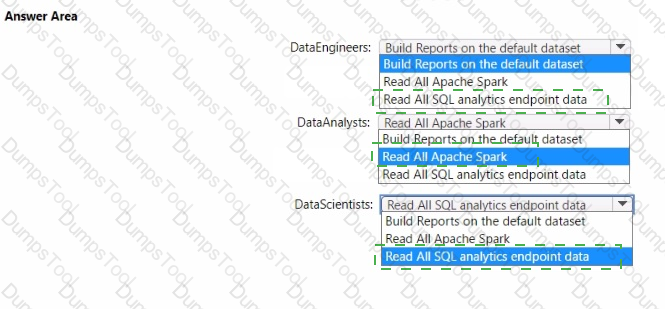
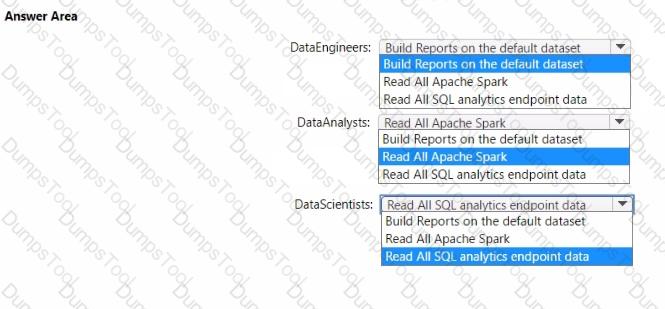
You to need assign permissions for the data store in the AnalyticsPOC workspace. The solution must meet the security requirements.
Which additional permissions should you assign when you share the data store? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
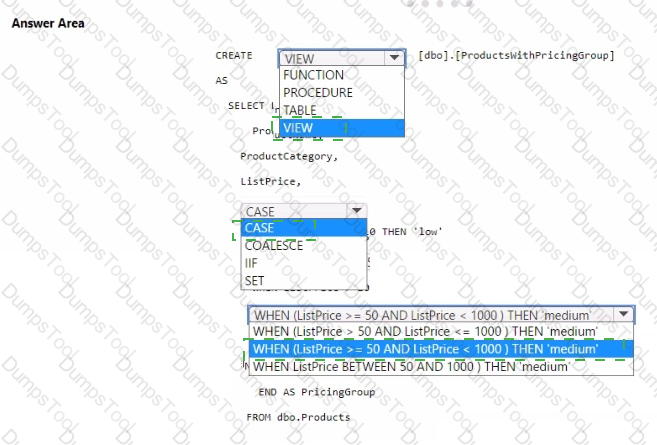
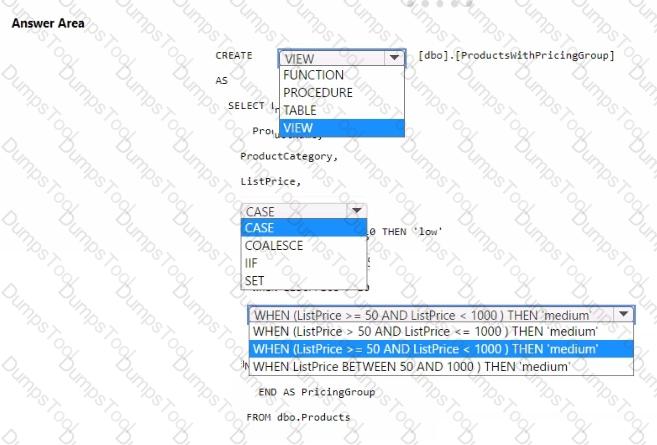
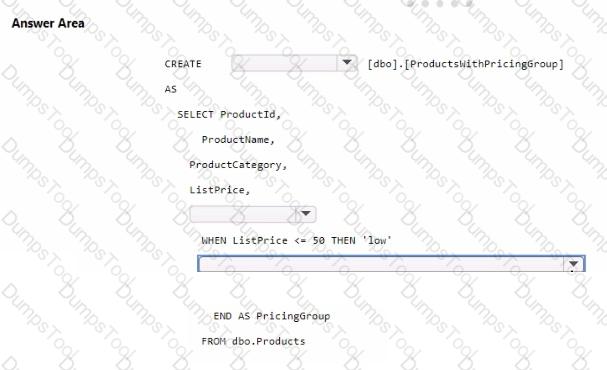
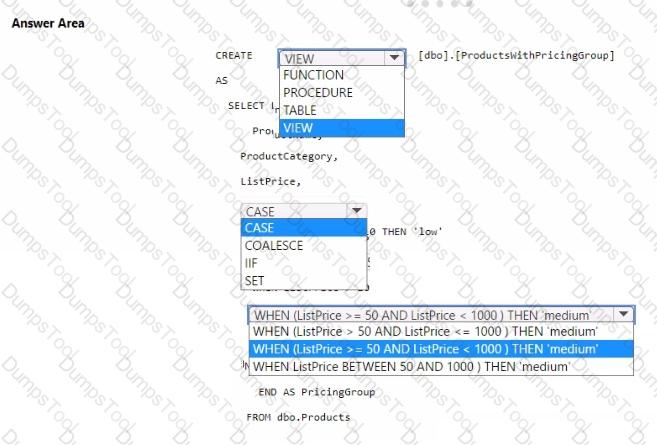
You need to resolve the issue with the pricing group classification.
How should you complete the T-SQL statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
You need to refresh the Orders table of the Online Sales department. The solution must meet the semantic model requirements. What should you include in the solution?
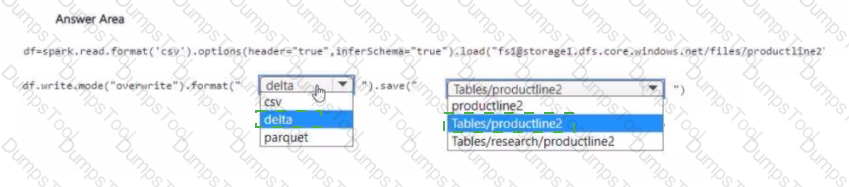
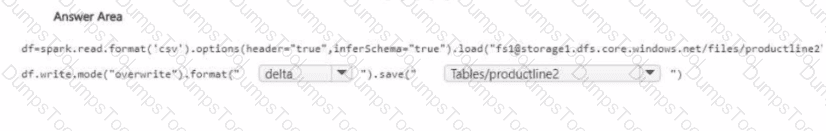
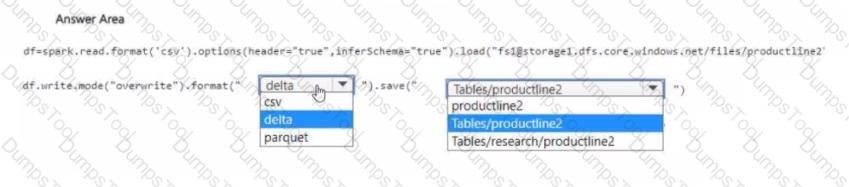
You need to migrate the Research division data for Productline2. The solution must meet the data preparation requirements. How should you complete the code? To answer, select the appropriate options in the answer area
NOTE: Each correct selection is worth one point.
You have a Fabric tenant that contains a semantic model named Model1. Model1 contains a fact table named FactSales. FactSales has a relationship to a dimension table named DimDate on a column named OrderDate.
To FactSales, you add a second relationship between FactSales and DimDate based on a column named ShippedDate.
You need to filter by using ShippedDate in a new report. The solution must NOT affect the function of existing reports.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct answer is worth one point.
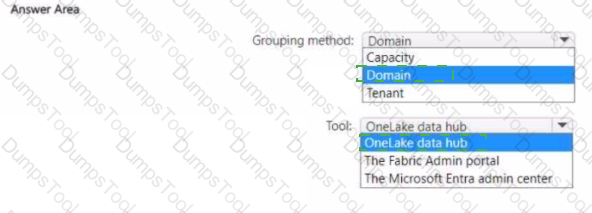
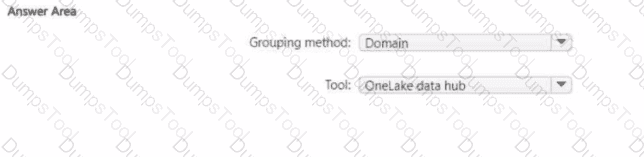
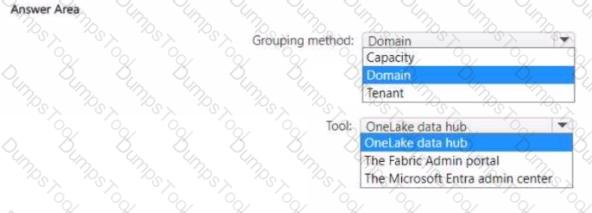
You need to recommend a solution to group the Research division workspaces.
What should you include in the recommendation? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
What should you use to implement calculation groups for the Research division semantic models?
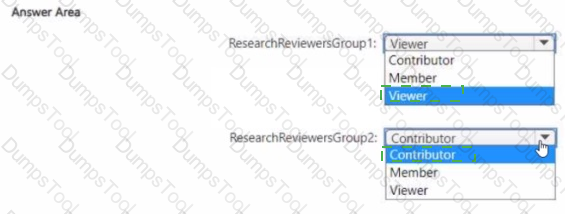
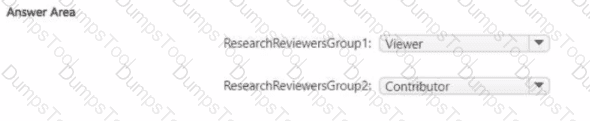
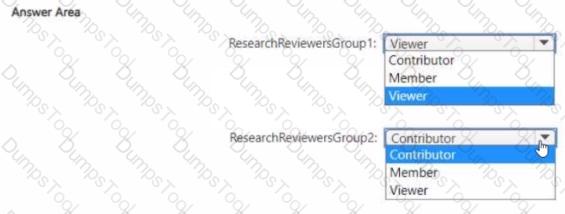
Which workspace rote assignments should you recommend for ResearchReviewersGroupl and ResearchReviewersGroupZ? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
You need to recommend which type of fabric capacity SKU meets the data analytics requirements for the Research division. What should you recommend?
You have a Fabric tenant tha1 contains a takehouse named Lakehouse1. Lakehouse1 contains a Delta table named Customer.
When you query Customer, you discover that the query is slow to execute. You suspect that maintenance was NOT performed on the table.
You need to identify whether maintenance tasks were performed on Customer.
Solution: You run the following Spark SQL statement:
EXPLAIN TABLE customer
Does this meet the goal?
You have a Fabric workspace named Workspace1.
Workspace1 contains multiple semantic models, including a model named Model1. Model1 is updated by using an XMLA endpoint.
You need to increase the speed of the write operations of the XMLA endpoint.
What should you do?
You need to ensure that Contoso can use version control to meet the data analytics requirements and the general requirements. What should you do?
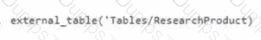
Which syntax should you use in a notebook to access the Research division data for Productlinel?
A)
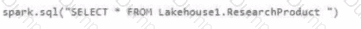
B)
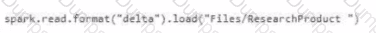
C)

D)
TESTED 03 Oct 2026